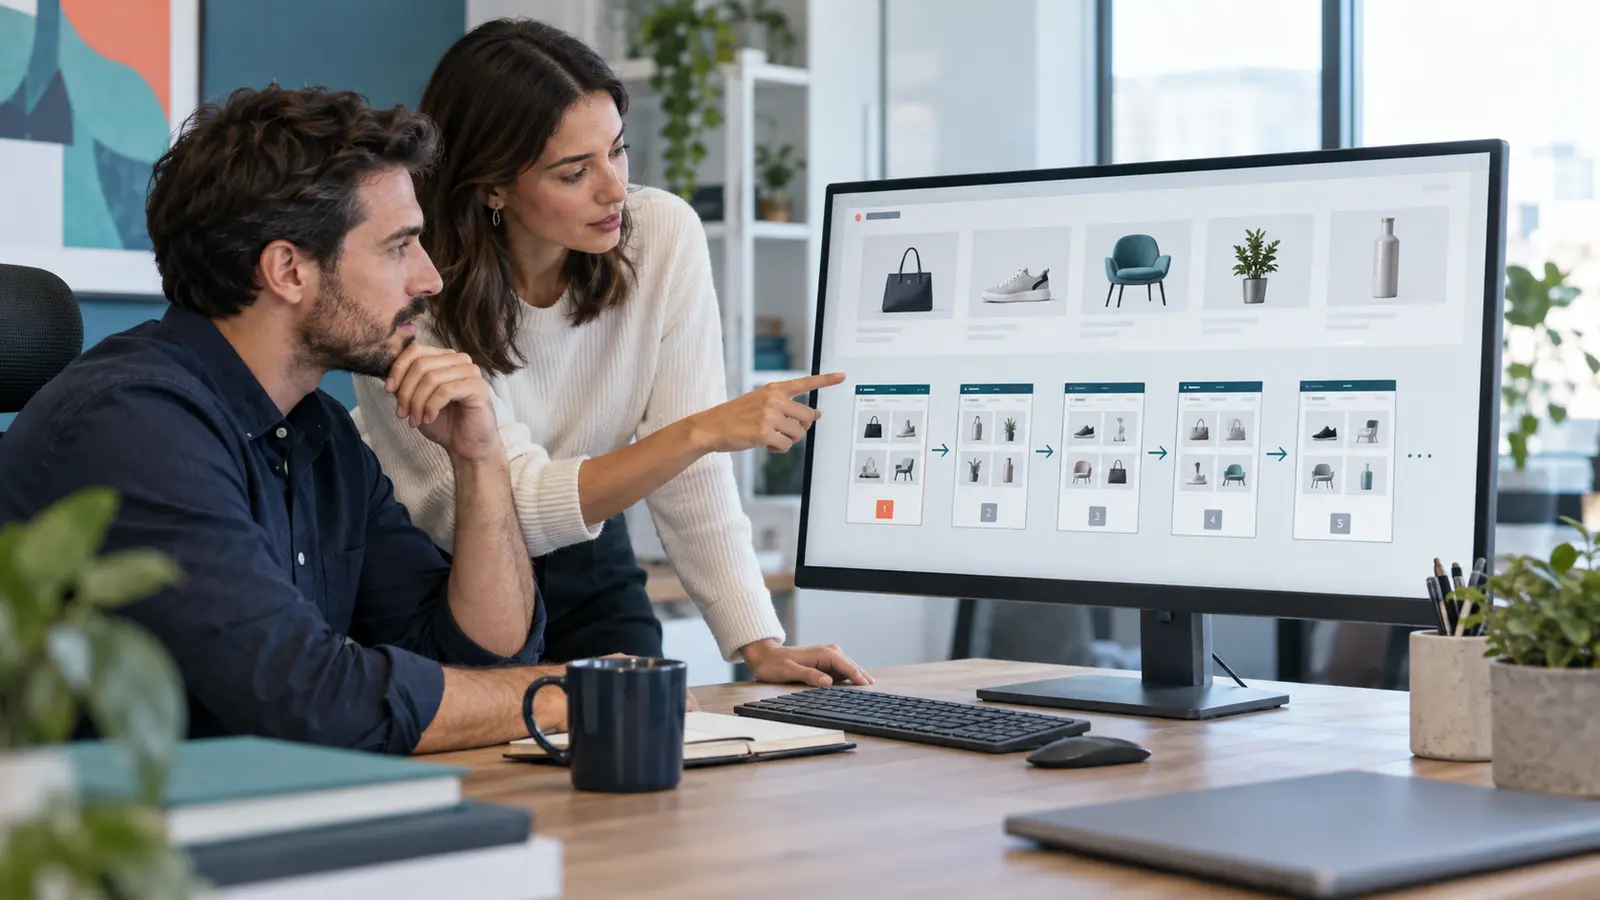
Pagination is not merely a row of page numbers at the bottom of a category. It is part of the route search engines use to reach products, articles, reviews and other items that do not appear on the first screen. A polished interface can still fail technically if those deeper items only exist after a click, scroll or JavaScript event that a crawler does not trigger.
Give every component page a stable URL, link the sequence with real HTML anchors, let each page canonicalize to itself and make every important item reachable without requiring a button click. Treat filters and sort orders separately from the core pagination sequence. Use infinite scroll or load more when it improves the experience, but support it with crawlable component pages.
What Pagination SEO Means
Pagination SEO is the practice of dividing a long collection into usable pages without hiding the items inside it from search engines. It applies to ecommerce category pages, blog archives, news listings, marketplace results, product reviews, forum threads and any interface that loads a large set in stages.
The first objective is discovery. Googlebot needs links that lead from the collection into deeper component pages and then into the individual items. The second objective is consolidation. The site should avoid multiplying the same collection through sort, filter, tracking and session parameters. The third objective is usability. People need to understand where they are, move backward, continue forward and return to a useful position.
This is why pagination belongs inside a broader technical SEO strategy. It connects information architecture, rendering, URL rules, internal links, crawl behavior and user experience. Fixing only the visual control rarely fixes the whole system.
What Google Actually Confirms
Google’s current pagination and incremental loading documentation gives unusually direct instructions. Each component page should have a unique URL. Pages should link sequentially using crawlable anchors. A component page should not canonicalize to page one. Fragments after a hash should not represent page numbers. Google also says it no longer uses rel="next" and rel="prev" to identify a series.
Google further explains that its crawlers generally do not click buttons or trigger JavaScript that depends on user actions. A load more control may be excellent for a shopper and invisible as a discovery route to a crawler. The solution is not to abandon the interface. The solution is to give every loaded segment a stable URL and connect those URLs through links Google can follow.
?page=2 URL represents another component in the primary collection. A URL such as ?sort=price-low often rearranges the same items. Google explicitly recommends avoiding indexation of unwanted filter and sort variations.
Fourteen Pagination SEO Best Practices
Use Real Crawlable Links
Build next, previous and page-number controls with an a element and a resolvable href. A styled button is fine visually, but the underlying navigation still needs a link.
Give Every Page a Stable URL
Use paths such as /category/page/2/ or a deliberate query parameter such as ?page=2. The server should return that component directly when requested.
Use Self-Referencing Canonicals
Page two normally points to page two, page three to page three and so on. Canonicalizing the series to page one conflicts with Google’s documented recommendation.
Link the Sequence in Order
Each page should link to the following page. Previous links help people and create a clear bidirectional route, while numbered links shorten the route to deeper components.
Keep the First Page Easy to Reach
Link collection components back to the first page. Google says this can emphasize the starting page as the preferable search landing page.
Never Put Page State After a Hash
A fragment such as #page=3 is not a separate crawlable document for Google. Use a server-addressable path or query parameter instead.
Do Not Depend on Rel Next
You may retain next and previous link relations for other consumers, but Google no longer uses them to understand the series. They cannot replace visible crawlable links.
Keep Essential Routes Unblocked
Do not disallow the only pagination route in robots.txt. A blocked page cannot be crawled, so Google cannot reliably inspect the item links it contains.
Choose Noindex With Evidence
A blanket noindex rule is not a universal pagination solution. First confirm whether deeper items have other strong crawlable routes and whether the component adds discovery value.
Control Filter and Sort Variants
Separate the primary page parameter from facets, tracking and ordering parameters. Decide which combinations deserve indexation and suppress the rest consistently.
Support Load More With URLs
When a button appends products, make equivalent component URLs available and link to them in the rendered document. Do not make a click the only route.
Render Critical Listing Links
Server rendering or reliable rendering ensures product and article links exist without waiting for a user event. Test the rendered HTML, not only what a browser user sees.
Reduce Excessive Crawl Depth
Use category, subcategory and editorial hub pages so important items are not 30 clicks from the start. Pagination should support architecture, not compensate for a flat, oversized archive.
Use Sitemaps as Support
Include canonical item URLs in XML sitemaps, but do not treat the sitemap as a replacement for internal links. Google uses links to discover pages and understand relationships.
Pagination Indexation Decision Table
The right directive depends on what a URL represents. “Index everything” and “noindex everything” are both poor default strategies.
| URL Type | Typical Treatment | Canonical Target | Reason |
|---|---|---|---|
| Main category page | Index and follow | Self | Primary landing page for the collection. |
| Page two and later | Usually crawlable and indexable | Self | Contains a distinct set of item links and supports discovery. |
| Useful facet with search demand | Index selectively | Self | Can serve a distinct intent when curated and internally linked. |
| Alternative sort order | Usually noindex or otherwise controlled | Clean equivalent where appropriate | Reorders substantially the same collection. |
| Tracking or session parameter | Do not index | Clean URL | Creates duplicates without user value. |
| Empty or impossible facet | Return a meaningful 404 or noindex based on behavior | None or valid equivalent | Prevents crawl traps and thin combinations. |
Canonical tags are signals, not instructions that repair every architecture mistake. Google’s canonicalization guide recommends consistent signals across links, sitemaps and canonical markup. If internal links point to parameter variants while canonicals point elsewhere, the site is sending mixed messages.
Pagination, Load More and Infinite Scroll
| Pattern | User Strength | SEO Risk | Safe Implementation |
|---|---|---|---|
| Numbered pagination | Clear position and total range | Deep click paths when the sequence is long | Stable component URLs, next links and selected jump links. |
| Load more | Keeps the user on one interface | Crawlers do not generally click the button | Provide linked component pages behind the experience. |
| Infinite scroll | Fast continuous discovery | New items may lack URLs and footer access can become difficult | Map segments to URLs, update history carefully and retain crawlable fallback links. |
Calling infinite scroll the “worst performer” is too broad. Google lists benefits and limitations for all three patterns. Infinite scroll can work when it exposes paginated component URLs, preserves navigation state and does not require Googlebot to scroll. The lazy-loading guidance is equally clear that important content should not depend on scrolling or clicking.
Canonical Tags for Paginated Pages
The simplest safe rule is that every primary component page canonicalizes to its own clean URL. If /chairs/?page=3 shows a different set of products from page one, it is not a duplicate of page one. Google’s pagination documentation explicitly says not to use the first page as the canonical for the sequence.
Page 2: canonical https://example.com/chairs/?page=2
Page 3: canonical https://example.com/chairs/?page=3
A view-all page can sometimes be useful, but it should not become the canonical automatically. It must load reliably, remain usable on mobile and represent the full collection without severe performance costs. For hundreds or thousands of products, that is often unrealistic.
Duplicate page-one URLs deserve special attention. If both /chairs/ and /chairs/?page=1 exist, pick one format, link to it consistently and redirect or canonicalize the duplicate. The same discipline should cover trailing slashes, uppercase variations and parameter order.
The Crawl Budget Reality
Pagination increases the number of URLs a crawler can visit, but that is not automatically waste. Those URLs may be the route to revenue-producing products or valuable articles. Google’s crawl budget documentation says dedicated crawl-budget management mainly applies to very large sites, sites with rapidly changing content or sites where a large share of URLs are not being crawled.
On many ordinary sites, duplicate faceted URLs, slow responses, redirect chains, soft errors and unstable rendering waste more crawling than a clean sequence. Start with server health, duplicate control and architecture. Do not remove useful routes simply to lower the URL count.
A sitemap can help Google discover canonical products, but Google’s link best practices still stress crawlable internal links. A product that exists only in an XML file is technically discoverable but weakly integrated into the site’s structure.
A Ten-Step Pagination SEO Audit
Use This Audit in Order
- Crawl the full site and save a baseline of discovered item URLs.
- Run a second crawl that excludes pagination URLs.
- Compare which products, posts or reviews disappear.
- Inspect the rendered HTML for real anchors with href values.
- Request page two and a deep page directly without cookies.
- Check status codes, canonicals and robots directives.
- Test the site with JavaScript disabled as a diagnostic, not as a perfect Google simulation.
- Map pagination, filters, sort orders and tracking parameters separately.
- Measure click depth from categories, hubs and XML sitemap coverage.
- Validate a sample in Search Console URL Inspection after deployment.
The exclusion crawl is valuable because it exposes dependency, not because every dependent page is automatically broken. If a product disappears when pagination is removed but remains strongly linked from a subcategory, a buying guide and a related-products module, the risk is lower. If it has no other internal route, pagination is critical infrastructure.
Use log files when the site is large enough to justify them. Logs show whether search crawlers request deeper components, waste time in parameter traps or stop early because of slow responses. Pair that evidence with Search Console, crawl data and business value. A technical SEO consultant should connect findings to inventory and revenue, not deliver a list of URL counts without context.
Search-Friendly Implementation Examples
Basic Numbered Pagination
Current page: a href="/chairs/?page=2" aria-current="page"
Next page: a href="/chairs/?page=3"
The exact design can vary. The important details are resolvable destinations, useful anchor text, a visible current state and direct server responses for every linked URL. Google’s documentation allows the same page title and description across the sequence, although adding “Page 2” can help analytics, browser tabs and human diagnosis.
Load More With a Crawlable Route
The interface may append page two into the existing view, but page two must still exist at a stable URL. Include a crawlable next link in the document and enhance it with JavaScript for users. If JavaScript fails, navigation should still work. If the browser history is updated, back and forward behavior should restore a meaningful position rather than dropping the visitor at the top.
Accessibility and User Experience
Use a labeled navigation region, mark the current page, preserve keyboard focus after content loads and announce meaningful updates to assistive technology. Avoid tiny targets and endless scrolling without a way to reach the footer. SEO and accessibility often converge here because both benefit from explicit structure and dependable navigation.
Nine Common Pagination Mistakes
| Mistake | What Can Go Wrong | Better Approach |
|---|---|---|
| Canonicalizing every page to page one | Distinct item sets are treated as duplicates. | Use a self-reference on each clean component. |
| Using only button clicks | Crawlers may never trigger the next set. | Expose linked URLs and progressively enhance them. |
| Blocking pagination in robots.txt | Google cannot inspect the page or its item links. | Keep essential discovery routes crawlable. |
| Putting page state after a hash | Components may collapse into one URL. | Use a server-addressable path or parameter. |
| Relying on rel next and rel prev | Google does not use them for sequence recognition. | Build real sequential links. |
| Generating unlimited parameter combinations | Crawl traps and duplicated collections expand. | Whitelist useful facets and control the rest. |
| Leaving deep pages dozens of clicks away | Discovery slows and internal prominence weakens. | Add subcategories, hubs and selected jump links. |
| Testing only in a visual browser | A polished interface hides missing rendered links. | Inspect source, rendered HTML and direct responses. |
| Treating sitemaps as architecture | Items remain poorly connected internally. | Use sitemaps as support, not replacement navigation. |
How Pagination Supports a Stronger Site
Good pagination does more than prevent orphan pages. It lets category pages distribute attention, gives crawlers repeatable routes and lets users explore without loading an unreasonable amount of content at once. It also makes audits clearer because each state has a stable address.
The larger lesson is that technical SEO works through systems. Crawlable pagination will not rescue thin product pages, inconsistent canonicals or weak categories. In the same way, strong backlinks and authority signals cannot help pages that the site hides behind inaccessible interactions. Discovery, quality, internal structure and external authority reinforce one another.
Frequently Asked Questions
What Is Pagination in SEO?
Pagination divides a large collection into a sequence of URLs. Pagination SEO ensures search engines can discover the sequence, crawl the item links and understand each component without creating unnecessary duplicate URLs.
Should Paginated Pages Be Indexed?
Google recommends unique URLs and self-referencing canonicals for pages in a sequence. The priority is to keep the components crawlable and control duplicate filters and sort orders separately.
Should Page Two Canonicalize to Page One?
No. Google explicitly advises against using page one as the canonical for the entire sequence. Page two normally canonicalizes to its own clean URL.
Does Google Still Use Rel Next and Rel Prev?
No. Google no longer uses these relations to identify a paginated series. They may help other systems, but they do not replace crawlable visible links.
Is Infinite Scroll Bad for SEO?
Not automatically. It is risky when extra items have no stable URLs or crawlable links. A robust implementation maps segments to URLs and works without requiring a crawler to scroll.
Can Google Click a Load More Button?
Google generally does not click buttons or trigger user-dependent actions. Provide crawlable component links or another server-rendered route to the additional items.
Can Pagination Use URL Fragments?
No. Google ignores fragments for page numbers. Use a path or query parameter that returns the component directly from the server.
Does Pagination Waste Crawl Budget?
Clean pagination is often useful discovery infrastructure. Crawl budget becomes a special concern mainly on very large or rapidly changing sites. Duplicate parameters and poor server performance are often more wasteful.
Should Paginated Pages Have Unique Titles?
Google says the same titles and descriptions may be used throughout a sequence. A page number can still make human analysis easier, but it is not required.
How Do I Test Pagination SEO?
Compare normal and pagination-excluded crawls, inspect rendered anchors, request deep components directly and verify status codes, canonicals, robots directives, internal depth and Search Console inspection results.
Related Cresto Digital Guides
Need a Pagination and Crawlability Review?
Cresto Digital can trace how crawlers move through your categories, facets and JavaScript interfaces, then turn the findings into an implementation plan your developers can use.
Talk to an SEO Specialist